Showing posts with label mrsa screening. Show all posts

Wednesday, 17 July 2013

UK police use powers to seize personal data at borders


UK police are using counter-terrorism laws to seize the mobile phones of people entering the UK and download their personal data, it has emerged.

This means police can stop anyone at random at UK air, sea and rail ports to seize and retain all the data on their mobiles phones, according to the Telegraph.

This can include call history, contact lists, photos and recent contacts, but not the content of any messages sent by text or email.

The reports say the powers are so broad that police do not even have to show reasonable suspicion for seizing a mobile phone and can retain the information for “as long as is necessary”.

The paper claims that up to 60,000 people a year are examined as they enter or return to the UK under powers contained in the Terrorism Act 2000, but said the number of data seizures is unknown.
The 2013 annual review of terrorism laws, due out this week, is expected to raise concerns over the broad powers granted by the Terrorism Act and call for proper checks and balances to prevent abuse.
Independent legal reviewer David Anderson QC said information downloaded from mobiles seized at ports has been useful in bringing terrorists to justice.

However, he said ordinary travellers need to know that their private information will not be taken without good reason, or retained by the police for any longer than is necessary.
Privacy International has raised concerns about the wide-ranging powers, saying nowhere in the UK do people have fewer rights than at the border.

“If you were on the other side of the border, the police would rightly have to apply for warrants and follow strict guidelines,” the group’s Gus Hosein told the Telegraph.

“Under law, seizing a mobile phone should be only when the phone is essential to an investigation, and even then certain rules should apply. Without these rules, everyone should be worried,” he said.

Privacy watchdog the Information Commissioner’s Office (ICO) is reviewing similar data seizure powers police can use within the UK, although they must have grounds for suspicion and the phone can be seized only if the owner is arrested.

Last year, it emerged that seven UK police forces had installed technology that allowed officers to download data from suspects’ phones, including London’s Metropolitan Police force.

At the time, police authorities said guidelines given to officers state that data extraction can happen only if there is sufficient suspicion that the mobile phone was used for criminal activity.

Telecoms M&A ‘flourishes’ in UK

The UK market for mergers and acquisitions (M&A) has taken a beating in the first half of 2013, but the telecoms sector has shone a light in otherwise gloomy statistics.

This was the finding of the latest report from Experian, which showed the number of M&A, alongside Equity Capital Market (ECM) transactions, in the UK fell by 17.3% this year when compared with the first six months of 2012 – down from 2,491 to 2,060.

Yet, while overall figures were down, the telecoms sector saw a huge rise in the value of deals done – up from £4.4bn in 2012 to £23.8bn in 2013. This positivity was reflected in Europe as a whole, with deal values up by 77% and the overall number done also increasing by 11.9%.

The biggest deal of someone buying into the UK market came with Liberty Global’s acquisition of Virgin Media, which closed in June for £15bn. Of the UK companies spreading their wings further afield, the biggest deal came with Vodafone’s purchase of German telecoms firm Kabel Deutschland for £6.6bn.
“Some sectors are further along the road to recovery than others and the strong activity we are witnessing in the telecoms and financial services sectors is encouraging,” said Wendy Driver, business development manager at Experian.

“[But] UK businesses still seem to be maintaining a watchful, wait and see, attitude towards M&A so far this year. Subject to the economic outlook continuing to improve, we would anticipate an increase in companies looking to grow by acquisition as we move into the second half of 2013.”

Matt Walker, principal analyst of networks for Ovum, said: “M&A is part of the natural growth and decline of the telecoms industry. There are always mergers, even during the relatively quiet quarters.”
However, he believed the strong North American market and weaker European outlook had encouraged companies to look at doing deals.

“The recent upswing is, most directly, due to North America. M&A has picked up there and [North American] merger deals are almost always fairly big,” he said.

“Markets overall are more stable than in recent past, and some stability around valuations is needed to facilitate M&A deals. [However], the health of telecom differs regionally, with North America and China much stronger than most other regions, and Europe especially weak.


“This sort of disparity can force some carriers to consider mergers, just as other more cash-rich rivals look for acquisition targets to gain scale.”

IT energy consumption lower than previously claimed

The average Briton spends only about 0.5% of their daily energy consumption on internet services, including everything from accessing the datacentre to using mobile devices, a study has found, debunking the myth that surging demand for consumer IT is hurting the environment.
A previous study, carried out earlier this year by the Centre for Energy-Efficient Telecommunications (CEET), summarised that access networks, not datacentres, are the biggest threat to the sustainability of cloud services. “This is because more people are accessing cloud services via wireless networks, and these networks are inherently energy inef?cient,” the study stated.

Datacentres are only part of a much larger cloud computing ecosystem. The network itself, and speci?cally the ?nal link between telecommunications infrastructure and user device, is “by far the dominant and most concerning drain on energy in the entire cloud system,” according to the CEET study.
“Our energy calculations show that by 2015, wireless cloud will consume up to 43TWh (terawatt hours), compared with only 9.2TWh in 2012 – an increase of 460%,” it stated.
This means an increase in carbon footprint from six megatonnes of CO2 in 2012 to up to 30 megatonnes of CO2 in 2015.
However, more recent research by industry body ESP KTN has debunked this myth. It found that households are actually using far less energy to maintain their digital lifestyles than originally thought.
The research assessed the energy cost of internet mediated transactions, such as downloading an album from iTunes or streaming a film.
The network, and speci?cally the ?nal link between telecommunications infrastructure and user device, is by far the dominant and most concerning drain on energy in the entire cloud system
CEET study
“Energy consumed in networks is utterly inconsequential to the energy consumed at the datacentre and the energy consumed in the home (for general cloud services),” wrote the ESP KTN study’s authors, Paul Krause and Kate Craig-Wood.
When looking at UK users’ daily carbon use, the average home broadband usage is 23GB per month, which equates to 2,000Wh (watt hour) per day based on the laptop user model. The average Briton consumes 195,000Wh per day of energy, and there are on average 2.3 people per household, so online activities account for perhaps 0.5% of our total energy footprint.
“The energy of our online lives is inconsequential compared to the great benefits to society,” wrote Krause and Craig-Wood.
Craig-Wood conducted this research as part of her PhD looking at cloud computing in relation to climate change. She said the study has clearly demonstrated that IT is not the enemy.
“A typical Briton spends 0.5% of their daily energy consumption on internet services, including everything from the datacentre to the laptop. Given that ICT is expected to save 16% of societal emissions by 2020 and the sector already contributes 10% to GDP, the climate impact of our industry is clearly not a significant concern at this stage," she said.
The study found that energy consumed in transferring data from a regional datacentre to a user is 1592Wh/GB.
“This is significantly lower than earlier published estimates, but this difference can be accounted for by efficiency gains over the last seven years,” said Krause.
Online activities account for perhaps 0.5% of our total energy footprint
ESP KTN study
“We are seeing a massive growth in the use of wireless networks for music and video streaming and downloading. But this is replacing the purchase and use of physical media, which is a much more energy-intensive activity,” he added.
As the consumer appetite for digital content grows, commentators have expressed fears about the environmental impact this surging demand for media consumption is creating, both in housing this data in datacentres – for example, Facebook alone handles 300 million photo uploads per day – as well as in consuming this data through cloud services via mobile devices.

But on the contrary, households are using less energy as digital content consumption grows, the latest study has shown.

Podcast: Key steps to big data security in hospitality

Hospitality is a sector that lends itself to big data analytics. Organisations can draw on multiple sources of customer information from many sources and on many subjects, ranging from room preferences to car hire and restaurant information.

At the same time, organisations may also provide access to systems to external partners, such as suppliers, but will also be required to hold credit card details securely, so big data security is a major concern also.
In this podcast, ComputerWeekly.com storage editor Antony Adshead talks with Vigitrust CEO Mathieu Gorge about big data security in hospitality and the key steps towards achieving it, including how data is classified and secured, as well as important steps to legal and regulatory compliance such as the PCI-DSS regulation.

Gorge: First of all, we should look at the specific challenges the hospitality sector might have with regards to data, and data that it might acquire; not just about its own employees and staff, but about customers and suppliers.

So, looking at customers first, a client of a hotel or restaurant or whatever, there are different types of data that you might acquire. There will be identity information, a passport or identity card, something that will allow a person to identify themselves as having booked a room, for example.
The confidentiality and integrity of the data must be maintained at all times Mathieu Gorge, Vigitrust
Then there’s going to be payment information, and there could be specific types of health information – dietary information or accessibility requirements, for example. You can see that this type of data has a value with regard to security, so the confidentiality and integrity of the data must be maintained at all times.
Then a hospitality organisation might be using a range of suppliers, some of which will need to access specific data. So you have to consider how to manage information that suppliers may gain access to.
Finally, most of the hospitality industry, especially hotels, will use a property management system that might be linked to additional services that the hotel might offer, such as access to wireless internet that might be free if you are a customer with a loyalty card.

So, you can see that the amount and different type of data that a typical hotel will actually deal with is, by nature, big data, so how they collect and classify that data is something that all security people, IT people and compliance people need to be aware of.

Gorge: The hospitality industry, given the nature of the services that it offers, needs to make sure that it classifies the information and data it holds about its customers in such a way that the lines of business that need to have access to it can do so securely and at the right time.

So, let me put that in perspective. In a hotel you will have additional services, like the rooms that people stay in, but also a bar, spa, restaurant, car valet service, car parking, and so each line of business may need access to payment information, but also to where the customer might be from or whether they are part of a loyalty scheme.

So, in terms of how that data is classified and secured, for hotels in particular as well as large chains of restaurants, there are specific challenges in how big data is structured. That’s why we talk about big data in hospitality; it’s all about managing unstructured data, making sure the right lines of business have access to it at the right time.
It’s always the same issue of striking the balance between operational improvements and security Mathieu Gorge, Vigitrust
One of the key challenges with storage for the hospitality industry has to deal with compliance with the Data Protection Act, and particularly compliance with the likes of PCI-DSS. That’s because most of the business relies on the fact that customers will be using credit cards to book in advance and pay when they leave the hotel, but also use that as an identification system when they move from one line of business within the hotel to another.

So, it’s very important that any type of payment data that needs to be stored is stored in compliance with PCI-DSS and that at if any given time the hospitality [organisation] needs to get some identification, like a passport or identity card, this is kept according to the requirements of the Data Protection Act.

Unfortunately, given the current economic climate, some hotels are not dedicating enough time or people to look after making sure that data is stored properly and access restricted on a need-to-know basis.

So, it’s always the same issue [of striking] the balance between operational improvements and security.

Having said that, the specific challenges with regard to data storage and data security in the hospitality
industry shouldn’t be underestimated. There is some good guidance from the Hospitality Networking Group, for example, and a number of LinkedIn groups for the hospitality sector. I’d highly recommend people joined those groups so they can educate themselves to make sure their data is stored properly.

LUN storage management for vSphere and Hyper-V

The LUN has long been a bedrock of storage configuration for physical servers with LUN storage partitions carved out from RAID groups to provide logical chunks of capacity for applications.
Now, virtual server environments can abstract the physical characteristics of a server into software and so provide increased scale and utilisation of hardware resources.

But, storage must still be provided to virtual server and virtual desktop machines, with the hypervisor taking on an important role as the virtualisation layer, abstracting physical storage resources to virtual devices.
So, what has happened to the LUN? That depends on the virtualisation environment you’re using.
Regardless of hypervisor type, the persistent retention of data needs some form of storage device, either a traditional hard drive or a solid-state disk (SSD). For block storage, VMware’s vSphere suite, including ESXi and Microsoft’s Hyper-V use fundamentally different approaches to presenting physical storage.
VSphere systems take LUNs configured on a storage array and format them with the VMware File System (VMFS). This is a proprietary file format used for storing virtual machine files that takes advantage of on-disk structures to support highly granular levels of object and block locking.
The reason this is necessary is that most vSphere deployments use a small number of very large LUNs, with each LUN holding many virtual machines. An efficient locking method is needed to ensure performance doesn’t suffer as virtual environments scale up.
A single virtual machine is comprised of many separate files, including the VMDK or Virtual machine Disk. A VMDK is analogous to a physical server hard drive, with a virtual guest on vSphere potentially having many VMDK files, depending on the number of logical drives supported, the number of snapshots in use and the type of VMDK.

For example, for thin provisioned VMDKs, where storage is allocated on demand, a guest hard drive will consist of a master VMDK file and many VMDK data files, representing the allocation units of each increment of space as the virtual machine writes more data to disk.

By contrast, Microsoft has chosen to incorporate all components of the virtual machine disk into a single file known as a VHD (virtual hard disk). VHD files are deployed onto existing Microsoft formatted file systems, either using NTFS or CIFS/SMB.

There is no separate LUN format for Hyper-V. VHD files allocated as thin volumes (known as dynamic hard disks) expand by increasing the size of the file and consuming more space on disk. Inside the VHD, Microsoft stores metadata information in the footer of fixed size VHDs and in the header and footer of dynamic VHDs.

VHDs have advantages over VMDKs and VMFS in block-based environments in that the underlying storage of the data is NTFS, Microsoft’s standard file system for storage on Windows servers. This means VHD files can easily be copied between volumes or systems by the administrator without any special tools (assuming the virtual machine isn’t running of course).

It also makes it easy to clone a virtual machine, simply by taking a copy of the VHD and using it as the source of a new virtual machine. This is particularly beneficial using the new deduplication features of Windows 2012 which can significantly reduce the amount of space consumed by virtual machines that have been cloned from a master VHD.
The aggregation of servers and desktops into virtual environments means that the I/O profile of data is very different to that of a traditional physical server. I/O workload becomes unpredictable as the individual I/O demands from virtualised servers can appear in any order and so are effectively random in nature.
This is referred to as the “I/O blender” effect and the result is that storage provisioned for virtual environments must be capable of handling large volumes of I/O and for virtual desktops, to cope with “boot storms”, which result from high I/O demand as users start their virtual PCs in the morning and close down at the end of the working day.

To guarantee performance, typical storage deployments will use a number of options:
All-flash arrays are becoming increasingly popular for virtual environments. For virtual servers, they provide consistent, predictable performance; for virtual desktops they handle the boot-storm issue with lots of I/O bandwidth.Hybrid flash arrays use a mix of traditional spinning media and solid state, targeting active I/O at the solid-state storage using dynamic tiering technology. This provides a more attractive price point than all-flash arrays, as many deployments have large amounts of inactive VM data.Advanced features – For vSphere these include VAAI (vStorage APIs for Array Integration) and for Hyper-V ODX (Offloaded Data Transfer). Both of these features offload repetitive tasks from the hypervisor and reduce the amount of data transferred over the storage network, when performing common tasks such as replicating virtual machines or initialising file systems.

Ultimately, provisioning storage for virtual environments is all about getting the right IOPS density for the capacity of storage being deployed. This may seem difficult to estimate but can be taken from existing physical servers as part of a migration programme, or by pre-building some virtual servers and measuring IOPS demand. For virtual desktops, a good estimate is around 5-10 IOPS per desktop, scaled up across the whole VDI farm. This would require additional capacity to be built in for boot storm events.
For block devices, LUNs can be presented using Fibre Channel, Fibre Channel over Ethernet (FCoE) or iSCSI. Fibre Channel and FCoE have the benefit of using dedicated host bus adaptors (HBAs) or CNAs (Converged Network Adaptors) that make it easier to separate host IP traffic from storage network traffic. However, there are still some important design considerations even where a dedicated storage network is available.
Firstly, there’s the option to present LUNs across multiple Fibre Channel interfaces for both resiliency and performance. We’ll take resiliency as a given, as that would be standard practice for storage administrators, but for performance, multiple HBAs (or dual-port HBAs) allow physical segmentation of vSphere and Hyper-V LUNs by tier for performance purposes.
This may not seem like the most logical approach, but bear in mind LUNs presented to vSphere and Hyper-V are typically large, and so queue depth to individual LUNs can become an issue, especially with workloads of different priorities. This can be especially important where high performance all-flash devices have been deployed. For iSCSI connections, dedicated NICs should be used and multipathed for redundancy. Both Microsoft and VMware have deployment guides to show how to enable iSCSI multipathing.

While on the subject, it’s worth discussing LUN sizes. vSphere (and less so Hyper-V) are limited in the number of LUNs that can be presented to a single hypervisor. Typically, storage for these environments is presented using large LUNs (up to 2TB) to maximise the presentable capacity. As a result, the users of that LUN, which could represent many hosts, all receive the same level of performance.

Creating many LUNs of 2TB in size is quite expensive in storage terms. So, thin provisioning on the storage array presents a useful way to enable LUNs to potentially expand to their full 2TB capacity, while enabling multiple LUNs to be presented to a host to ensure I/O is distributed across as many LUNs as possible.
The grouping of storage for hypervisor guests at the LUN level represents a physical restriction on delivering quality of service to an individual virtual machine; all guests on a LUN receive the same level of performance.
Microsoft recommends using a single LUN per VM, which may be restrictive in larger systems (and certainly represents a significant management overhead), but is still possible to achieve.

VMware has stated its intention is to implement vVOLs – virtual volumes – to abstract the physical characteristics of the virtual machine storage from the storage array to the hypervisor. This would enable better granularity in terms of prioritisation of virtual machines and their I/O workload, even when they exist on the same physical array.


But while some companies focus on removing the storage array completely, it’s clear there are benefits in retaining an intelligent storage array, one that understands and can communicate with the hypervisor. 

Cloud databases less of a leap for users now, but some hurdles remain

With the growing adoption of cloud-based applications, it's natural that cloud databases would follow. Not that long ago, cloud-based database offerings were very limited -- so much so that organizations really didn't have a compelling reason to embrace them, other than for exploratory purposes. But in recent years, the landscape has changed: The number of available products and services has expanded significantly, as have their capabilities, reliability and application support.

Initial cloud offerings often were nothing more than a service provider running a database for an organization in a virtual machine on the provider's network. That shifted the database system off-premises, eliminating the capital costs associated with it and converting the outlay still required to operating expenses -- i.e., the service provider's charges for hosting the system. The benefits were purely economic in nature, and the user organization typically still needed to manage the database itself.

Now there's a large variety of cloud database options for IT managers and data management professionals to consider. Oracle, IBM and other database vendors make their software available for deployment in private clouds or on public cloud services, such as Amazon's EC2 and Microsoft's Windows Azure. Database as a Service platforms let users set up databases in the cloud without having to install or manage any software. Managed hosting services blend those two approaches: Service providers deploy database instances on their systems for users and manage the environments as well.

Both commercial and open source databases are available for use in the cloud; the choices also include a mix of mainstream SQL-based relational databases and schema-less NoSQL technologies that increasingly are being embraced for use in big data analytics applications. Even data warehouses can be stood up in the cloud, a point embellished by Amazon's announcement of its Redshift data warehousing service in late 2012.
The primary business drivers for adopting cloud-based databases are anticipated cost savings, increased flexibility and reduced database administration and systems management requirements. Another common driver is a decision by corporate and IT executives that deploying and managing database technologies in-house isn't strategic to a company's business and can be farmed out to a service provider.

The vendor sales pitch that cloud databases are more cost-effective and less resource-intensive than on-premises products, resulting in a lower total cost of ownership, may well be true. But cloud services and tools do cost money (as they should), so it's incumbent upon IT managers to do a return on investment (ROI) calculation comparing the various options -- including sticking with on-premises software.

The deployment flexibility made possible by cloud computing can factor into the ROI equation. With cloud database services, organizations can scale their database instances and processing capacity up or down as business requirements dictate, paying for additional technology resources only when they're needed instead of having to worry about buying new hardware and software, installing it in time to meet increased demands and then being saddled with it if those demands dissipate. The diminished admin burden is another potential ROI booster: Database configuration, backups, mirroring, uptime and disaster recovery procedures, software updates, and other tasks can all be redirected from internal database administrators to cloud service providers, as can systems management workloads.

Of course, there are some issues to take into account as well. Data security, privacy and regulatory compliance concerns needn't be the cloud showstoppers they often were treated as in the past, but they still need to be addressed before taking the leap and putting databases in the cloud.

Many IT managers remain reluctant to send important business data outside the corporate firewall. In addition, privacy laws and security regulations, particularly in Europe, restrict where data can be kept -- a possible complication with cloud services that run on systems distributed across data centers in various locations, including different countries. As the use of cloud databases has increased, so too has the ability of service providers to support the levels of security and privacy needed by almost all enterprises. In fact, cloud services may well be more secure than many corporate networks are -- after all, a cloud provider's business reputation rides on having robust security and privacy protections. But companies looking to take advantage of the cloud need to determine their security and compliance requirements up front and work closely with providers to ensure successful implementations.

Other issues that must be addressed before deploying cloud database software or services include integration with on-premises databases and applications and ensuring that sufficient network bandwidth is available to support the data needs of business users. If a company is primarily running cloud-based applications or is looking to collect big data and other information from external sources, cloud databases are an attractive option, and integrating them with existing systems might not be a big hurdle to get over. But if most applications are still on in-house systems, the integration demands could be high -- and keeping databases in-house as well might be the more appropriate way to go.


Similarly, if network bandwidth is limited and users need to download significant amounts of data for business intelligence and analytics applications, on-premises databases likely are called for. Database location must be transparent to end users; all they care about is being able to access data when they need it, no matter where it's coming from. Assuming that there is enough bandwidth and the other issues can be dealt with, there's no reason why that place can't be the cloud.

Tablet jackpot spoiler leads to FAST audit at London bingo club

London Palace Bingo Club IT director Chris Pugh took a gamble when he purchased tablet PCs direct from a Chinese manufacturer.
The gamble did not pay off, however, as a Federation Against Software Theft (FAST) audit subsequently identified significant under-licensing of Microsoft products at the club.

As a result, London Palace Bingo Club bought a Microsoft Open Licence for 255 Windows Pro 8 products to cover the tablet.
"We looked at purchasing hardware direct from manufacturer to lower our total cost of ownership and believed the pre-installed software was fully-licensed," said Pugh.
"The information we were given was incorrect, however, and the FAST investigation highlighted the risks involved in dealing direct with manufacturers in China. It was an honest mistake on our behalf and we welcomed FAST's intervention, which has improved our understanding of the risks and resulted in positive changes to our procurement process and software asset management," he added.
Alex Hilton, CEO of FAST, said: “We would recommend that any business considering cutting costs by buying and using cheaper Chinese products be aware that there is very often a highly complex and convoluted supply chain, with goods passing through several suppliers before they reach the ultimate end user.
"We would urge consumers to think again at the very least, and check the legality of the licences any product purports to have.”

As Computer Weekly has previously reported, the software industry needs to work with users to make terms and conditions of software licensing clearer.

Microsoft slashes the price of its Surface tablet

Microsoft has cut the price of its flagship Surface tablet. The 32GB Surface RT has dropped from £400 to £279, while the 64GB RT’s price was also cut by 30% to £359.
But the Microsoft’s Surface Pro has not seen any changes to its price. The full Windows 8 tablet starting price remains at £719 for 64GB.

The devices were launched at the end of last year to challenge Apple and Android tablets, which dominated the market.
Tablet shipments have grown 142% year-on-year in the first quarter of 2013. According to IDC, 49.2 million tablets were shipped in Q1 and 900,000 of those units were Surface RT and Surface Pro devices.
The change in pricing comes days after CEO Steve Ballmer announced plans to reinvent Microsoft with a big push to develop hardware.
Expanding beyond the Xbox and the Surface tablet, Ballmer plans to grow consumer hardware and enterprise services. “We will design, create and deliver, through us and through third parties, a complete family of Windows-powered devices,” he said.

Part of this push with devices in the consumer sector will also occur in the enterprise market.

Remove - Subscribe to: Posts (Atom) from Blogger

In many Blogger templates there is a "subscribe to: Posts (Atom)" link, so that the blog visitors can subscribe to the Atom feeds. Considering the fact that many readers use RSS for their blog feeds, many of you could find this link pretty useless. Moreover it occupies space at the bottom of the template and it doesn't look nice at all. In this case you might want to remove it.

How to remove subscribe to: Posts (Atom) link? 


Step 1. Go to your Dashboard > Template > Edit HTML (click on Proceed button if needed)


Step 2. Select "Expand Widget Templates"


Step 3. Find (CTRL + F) this line:

<b:include data='feedLinks' name='feedLinksBody'/>

Step 4. Remove it and Save Template.

This should remove subscribe to: posts (atom) link.

Tuesday, 16 July 2013

Add Random Posts Widget to Blogger

The Random Posts Widget will show random posts you have added to your blog. The main advantages of this widget is that it is loading pretty fast and shows thumbnails of your posts too, along with the comments link.


How to add Random Posts Widget to Blogger

Step 1. Log in to Blogger Dashboard, and select Template > Edit HTML (click on Proceed button if needed)


Step 2. Select "Expand Widget Templates"

Step 3. Find (CTRL + F) the following tag:

]]></b:skin>

Step 4. Just above it, paste the code below :

#random-posts img{float:left;margin-right:10px;border:1px solid #999;background:#FFF;width:36px;height:36px;padding:3px}

Step 5. Save Template.

Step 6. Go to Layout, click on Add a Gadget 


random posts widget, random blogger

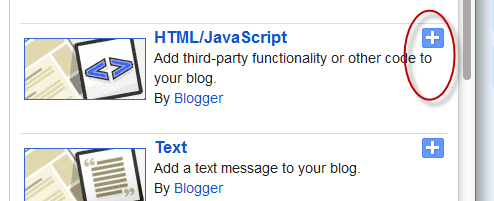
Step 7. Add a new HTML/JavaScript Gadget
random posts blogger

Step 8. Paste the following code in the empy HTML box:

<ul id='random-posts'>
<script type='text/javaScript'>
var rdp_numposts=5;
var rdp_snippet_length=150;
var rdp_info='yes';
var rdp_comment='Comments';
var rdp_disable='Comments Disabled';
var rdp_current=[];var rdp_total_posts=0;var rdp_current=new Array(rdp_numposts);function totalposts(json){rdp_total_posts=json.feed.openSearch$totalResults.$t}document.write('<script type=\"text/javascript\" src=\"/feeds/posts/default?alt=json-in-script&max-results=0&callback=totalposts\"><\/script>');function getvalue(){for(var i=0;i<rdp_numposts;i++){var found=false;var rndValue=get_random();for(var j=0;j<rdp_current.length;j++){if(rdp_current[j]==rndValue){found=true;break}};if(found){i--}else{rdp_current[i]=rndValue}}};function get_random(){var ranNum=1+Math.round(Math.random()*(rdp_total_posts-1));return ranNum};
</script>
<script type='text/javaScript'>
function random_posts(json){for(var i=0;i<rdp_numposts;i++){var entry=json.feed.entry[i];var rdp_posttitle=entry.title.$t;if('content'in entry){var rdp_get_snippet=entry.content.$t}else{if('summary'in entry){var rdp_get_snippet=entry.summary.$t}else{var rdp_get_snippet="";}};rdp_get_snippet=rdp_get_snippet.replace(/<[^>]*>/g,"");if(rdp_get_snippet.length<rdp_snippet_length){var rdp_snippet=rdp_get_snippet}else{rdp_get_snippet=rdp_get_snippet.substring(0,rdp_snippet_length);var space=rdp_get_snippet.lastIndexOf(" ");rdp_snippet=rdp_get_snippet.substring(0,space)+"&#133;";};for(var j=0;j<entry.link.length;j++){if('thr$total'in entry){var rdp_commentsNum=entry.thr$total.$t+' '+rdp_comment}else{rdp_commentsNum=rdp_disable};if(entry.link[j].rel=='alternate'){var rdp_posturl=entry.link[j].href;var rdp_postdate=entry.published.$t;if('media$thumbnail'in entry){var rdp_thumb=entry.media$thumbnail.url}else{rdp_thumb="https://blogger.googleusercontent.com/img/b/R29vZ2xl/AVvXsEg9cQepOiQ9FHQ7boSCvAfHtleMpgGxceSlLxdQfjCOEtsQPs3gNwD2jH9WwgXwKX2foophwAmBLg5wZVYvQWCgJA1Oxjv4kAd0o736ilSXrKNzLfjLBzXcOWCvUrUpvVM3aYcgZR2dulU/s1600/default.jpg"}}};document.write('<li>');document.write('<img alt="'+rdp_posttitle+'" src="'+rdp_thumb+'"/>');document.write('<div><a href="'+rdp_posturl+'" rel="nofollow" title="'+rdp_snippet+'">'+rdp_posttitle+'</a></div>');if(rdp_info=='yes'){document.write('<span>'+rdp_postdate.substring(8,10)+'/'+rdp_postdate.substring(5,7)+'/'+rdp_postdate.substring(0,4)+' - '+rdp_commentsNum)+'</span>'}document.write('<div style="clear:both"></div></li>')}};getvalue();for(var i=0;i<rdp_numposts;i++){document.write('<script type=\"text/javascript\" src=\"/feeds/posts/default?alt=json-in-script&start-index='+rdp_current[i]+'&max-results=1&callback=random_posts\"><\/script>')};
</script>
</ul>

Note: Replace no. 5 with the number of posts you want to be show.

Step 9. Press Save and Enjoy!